Buying GuideGuide
Laptop Specs for Running AI Models Locally
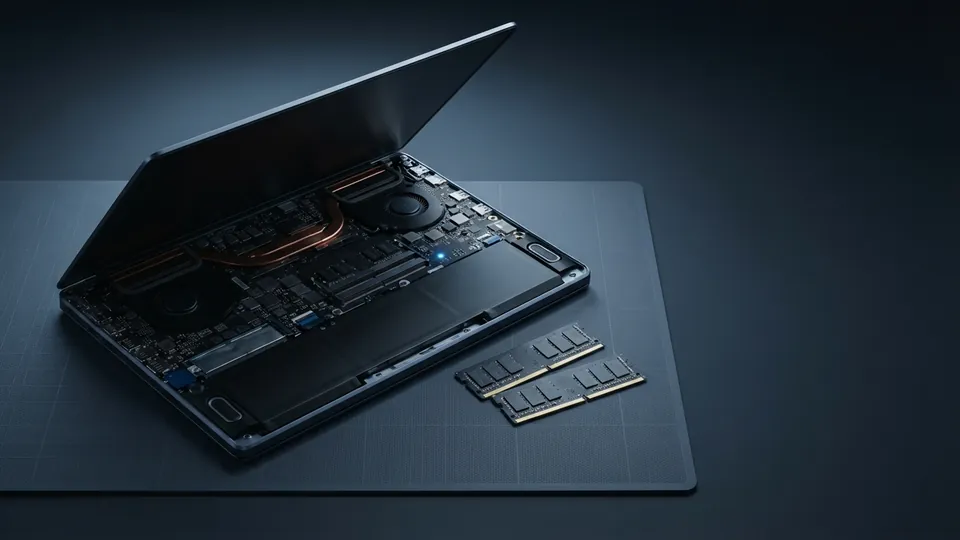
Running a language model on your own laptop keeps every draft on the machine, works on a train with no signal and costs nothing per word. Whether it is pleasant or painful comes down to two numbers most spec sheets bury: how much memory the model can use, and how fast that memory is.
On this page
Why memory decides everything
A language model is, in hardware terms, a very large table of numbers that has to sit in fast memory while it works. Every word it writes requires reading most of that table once. That gives two hard limits. First, the model has to fit: if it does not, it either refuses to load or spills onto the SSD and slows to a crawl. Second, the speed at which it produces text is roughly the speed at which the laptop can read its memory, divided by the size of the model. Processor clock speed, core count and the headline benchmark scores that decide a spec sheet comparison matter far less here.
Models are usually shared in quantised form, which stores each number in 4 to 8 bits instead of 16. Quality drops a little and memory use drops a lot. The rule of thumb in the spec card works well in practice: a model with 8 billion parameters at 4 bits needs about 4 GB for the weights, plus working memory for the text it is reading, so budget 5 to 6 GB. Your operating system, browser and editor need their own 6 to 8 GB on top.
| Model size | Memory at 4-bit | Laptop memory to be comfortable | Typical use |
|---|---|---|---|
| 1 to 3 billion parameters | 1 to 2 GB | 8 to 16 GB | Autocomplete, short rewrites, summaries of a page |
| 7 to 8 billion | 4 to 6 GB | 16 GB | General drafting help, outlining, tone changes |
| 13 to 14 billion | 8 to 10 GB | 32 GB | Longer drafts, better instruction following |
| 30 to 35 billion | 18 to 22 GB | 48 to 64 GB | Close to cloud quality for many writing tasks |
| 70 billion and up | 40 GB or more | 96 GB or more | Specialist machines only |
Memory bandwidth: the number to look for
Bandwidth is measured in gigabytes per second and is rarely printed on the box, but it is easy to look up from the memory type and the processor. Ordinary dual-channel laptop memory delivers roughly 60 to 100 GB per second. Laptops that use wide unified memory shared by the processor and graphics reach 120 to 400 GB per second or more depending on the tier, and a discrete graphics chip reads its own memory at 250 to 500 GB per second or more. As a ceiling, a 5 GB model on a 100 GB per second machine cannot exceed about 20 words per second, and real results land at roughly half that. Ten words per second reads comfortably; three feels like watching someone type.
Graphics chips, shared memory and NPUs
A discrete graphics chip is fast but its memory is separate and small, typically 6 to 16 GB on laptops. A model that fits entirely inside it runs quickly; one that does not has to be split, and the slower half sets the pace. That is why a thin machine with 32 GB of fast unified memory can outpace a heavier gaming laptop with a powerful but small-memory graphics card on larger models, while the gaming machine wins on models that fit its card. Neural processing units (NPUs), now advertised on many laptops, are efficient at small background tasks such as live captions and noise removal; support for running full writing models on them is improving but uneven, so treat an NPU as a bonus rather than the reason to buy.
Heat, battery and noise
Generating text keeps the memory and processor fully busy, which is exactly the load that makes a laptop hot. Expect the fans to spin up within a minute on a thin machine and battery life to fall to two or three hours of continuous generation. For long sessions use the laptop on a desk with the vents clear, plugged in, and consider capping the charge level. The guide to laptop heat and safety explains the temperatures that are normal and the ones that are not.
Storage and the rest of the spec sheet
Each model file is 2 to 10 GB for the sizes most people use, and it is easy to collect several while experimenting, so 512 GB is the practical minimum and 1 TB is better. Loading a model from a fast NVMe SSD takes seconds; from a slow drive it takes long enough to be irritating every time. Everything else on the sheet matters as it would for any writing laptop: a good keyboard, a screen you can read for hours, and a weight you are willing to carry.
This guide extends the laptop buying advice in this section. The general method in reading a laptop spec sheet still applies to everything except memory, and if weight matters as much as speed, check the trade-offs between laptop sizes before choosing a 16 inch machine for its larger memory options. Once you have the hardware, the offline assistant setup guide covers the software.
Common questions
Can a laptop with 8 GB of memory run a local AI model?
Only the smallest models, and only with little else open. It is fine for trying the idea; for daily writing help, 16 GB is the realistic floor.
Is a gaming laptop good for local AI?
It is good for models that fit in the graphics card's own memory, which on most laptops means up to about 8 billion parameters. Larger models are often faster on a machine with a large pool of fast unified memory.
Do I need an NPU?
No. NPUs help with small built-in features. Local writing models run on the processor and graphics today, with NPU support arriving gradually.
Will running models wear out my laptop?
No more than any sustained heavy load such as video export or gaming. Keep the vents clear and it will run within its designed limits.
How much storage do models take?
Between 2 and 10 GB each for common sizes, and 20 to 40 GB for the largest ones people run on laptops.
Sources
- Apple Support: MacBook Pro (14-inch, M4 Pro or M4 Max, 2024) Tech Specs: published unified memory bandwidth figures.
- Micron: LPDDR5X: lpddr5x laptop memory data rates.
- Hugging Face: Quantization overview: storing model weights in 4 to 8 bits to cut memory.
- arXiv: QLoRA, Efficient Finetuning of Quantized Models: 4-bit quantisation keeps quality close to 16-bit.
Also consulted: Model developers' published parameter counts and quantised file sizes for open-weight models, 2024 to 2026; Processor and memory makers' published memory bandwidth specifications for current laptop platforms; JEDEC standards for LPDDR5 and LPDDR5X memory.